Metrics, logs and traces on one timeline, stored in your own cluster and read by your
browser directly. Your telemetry never passes through our servers.
OpenTelemetry in · Kubernetes · read-only MCP for your agents
Our own Poet, live
drag to zoom · double-click back
Reading our own Poet…
Your data stays home.
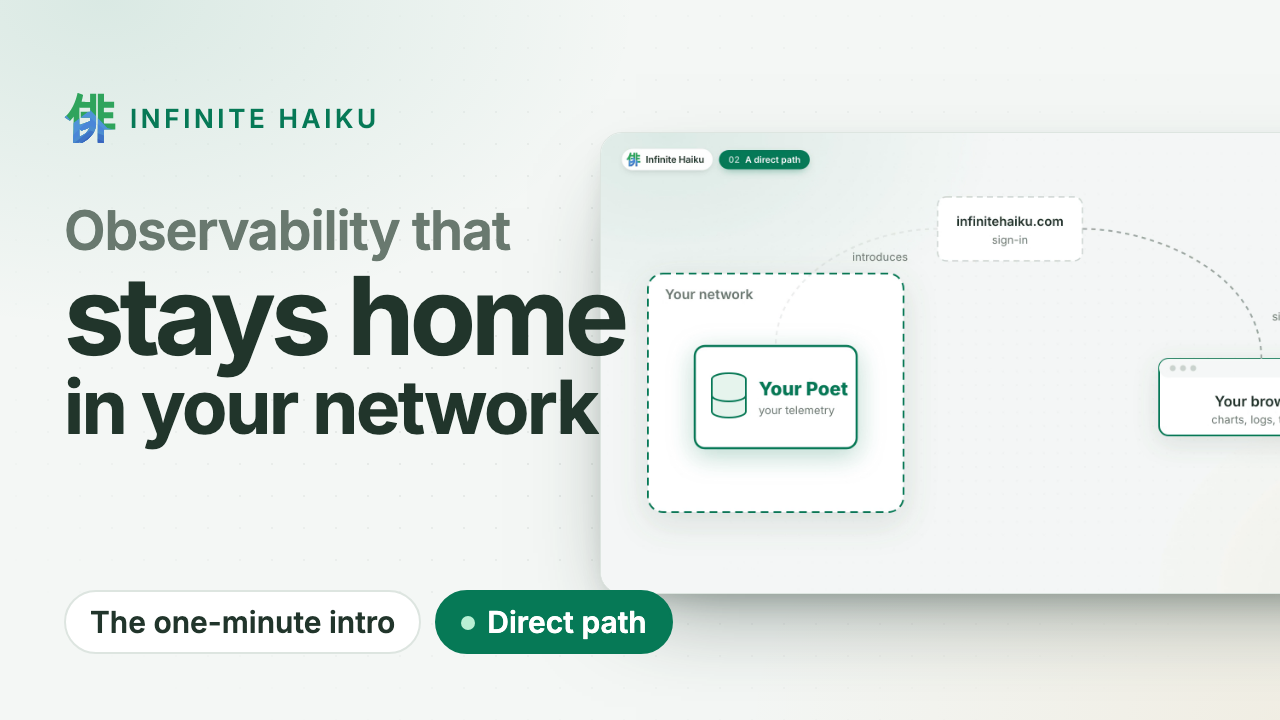
The datastore runs in your Kubernetes cluster or on your Linux machines. We sign you in and introduce your browser
to it; the data goes straight to you over an encrypted channel. No egress bill to ship telemetry
out, and nothing at our end to leak.
Walk into the timeline.
Every series of a service at once, drawn on your GPU. Zoom in and the detail follows; open a
request and see its log lines and the change behind it. Missing data is shown as missing, never
as zero.
Your agents investigate.
A read-only door (MCP) lets the coding agent you already use search, follow a request and read
the same numbers as your charts. No vendor AI, no per-investigation fee.
How it works
1A Poet in your cluster. Our datastore runs where your services run and
takes their OpenTelemetry. Read-only, one namespace.
2You sign in at infinitehaiku.com. Our web service checks who you are and
introduces your browser to your Poet. That is all it sees.
3Your browser talks to your Poet directly. An encrypted peer-to-peer
channel (WebRTC). The numbers never pass through our servers.
Infinite Haiku in one minute · plays from YouTube (youtube-nocookie.com)
Proof, not promises
Measured: 500,000 tasks from 200 workers over five hours, drawn at
1.1 ms of CPU per frame.
This site's own requests, live: the same public view you can give your customers.
Alerts in your network. Evaluated inside your own Poets.
Public status pages. Share a live dashboard without sharing access.
Kernel faults on the timeline. Memory errors, silent out-of-memory kills and disk errors, per node.
Flat CHF 5 per user account and month. Nothing per gigabyte, host or event.
Don't trust us: watch it yourself. Your Poet shows every connection and its bytes, peer to peer or to us. See how
Join the free pilot.
Expert help on your systems. Leave anytime: delete the Poet, one command.
Once we open to the public: two months free, then a flat CHF 5 per user account and month. How the pilot works ·
Security
Some of what gets blamed on “flaky” software is the hardware: a memory
bit that flips, a process killed and quietly restarted, a disk that logs
errors for weeks. A test crash on our own build server taught us how
easy that is to miss, and changed what Infinite Haiku (IH) watches on
every node.
Three crashes, three places
Our build server is a 32-core machine in the lab cluster that compiles and
tests every change. On 2026-10-12 one run of our datastore’s test suite
(Poet, about a thousand tests) died with a segfault and no Rust message.
Rust code doesn’t do that on its own, so we went looking for the bug. We
pulled the crash records from the machine and turned the addresses into
function names. Each crash was somewhere else:
inside the memory allocator, freeing memory as a test finished;
walking an ordered map;
serialising a metric definition.
Ten more full runs of the same binary under a debugger: no crash. The test
that died passed on its own. Code bugs repeat; these didn’t.
Ask the machine, not the code
The kernel log of the build server held 22 crashes since 29 September, and
most were not ours: the Rust compiler, the LLVM optimiser, a video encoder.
Programs that share no code were dying at unrelated addresses.
Then a direct test. We wrote patterns to memory and read them back, on two
groups of cores at the same time, for 15 minutes:
Test
Result
CPU only, results checked, 10 min, two cores
clean
Memory, results checked, 15 min, cores 0–2
clean
Memory, results checked, 15 min, cores 8–10
6 memory errors (bits read back flipped)
The machine’s memory has no error correction, so nothing had ever reported
a flipped bit. The data was simply wrong, now and then: a compiler cache
here, a test binary there. The fix belongs to the machine, and the
hardware stays in the lab on purpose: a faulty part is a free test case
for an observability product.
What IH watches now
The lesson for a monitoring tool is uncomfortable: the evidence sat in the
kernel log, and nothing we ran looked there. So IH now does. A new Muse
(IH’s name for a telemetry source) runs on every node, reads the kernel’s
log read-only, without root or extra privileges, and sends each fault to
the Poet as an event on that node, at the moment the kernel logged it:
segmentation faults and protection faults, with the program, the library
and the CPU core;
machine-check and memory-controller errors, where the hardware reports
them;
disk and filesystem errors;
out-of-memory kills.
It also counts faults per node and per core, so a dashboard can show
“which cores keep crashing” beside the services running on them. Our
build server’s pattern would have been visible on the first day: most
crashes landed on three of its sixteen cores.
Its first minutes on our own cluster showed something nobody had noticed:
our datastore had been killed for running out of memory 20 times on one of
the small lab nodes since it last booted. It restarted quietly each time.
Now each kill is an event on the timeline, next to the memory graph that
explains it.
What this means for you
Silent memory errors, killed processes that restart quickly, a disk that
logs errors for weeks: with IH they show up where you already look, on the
same timeline as your services, per node and per core. The Muse reads a
log your nodes already write; it needs no root access and runs within a
tenth of a core and 128 MB, small enough for a Raspberry Pi.
Want IH to watch your own nodes? Ask us for a pilot.
Welcome back
No account yet? Write to us: during the pilot we set up your organisation with you.